Riccardo Di Francesco
  • Research
  • Software
  • Teaching
  • Talks
  • CV

Research

Research

Publications

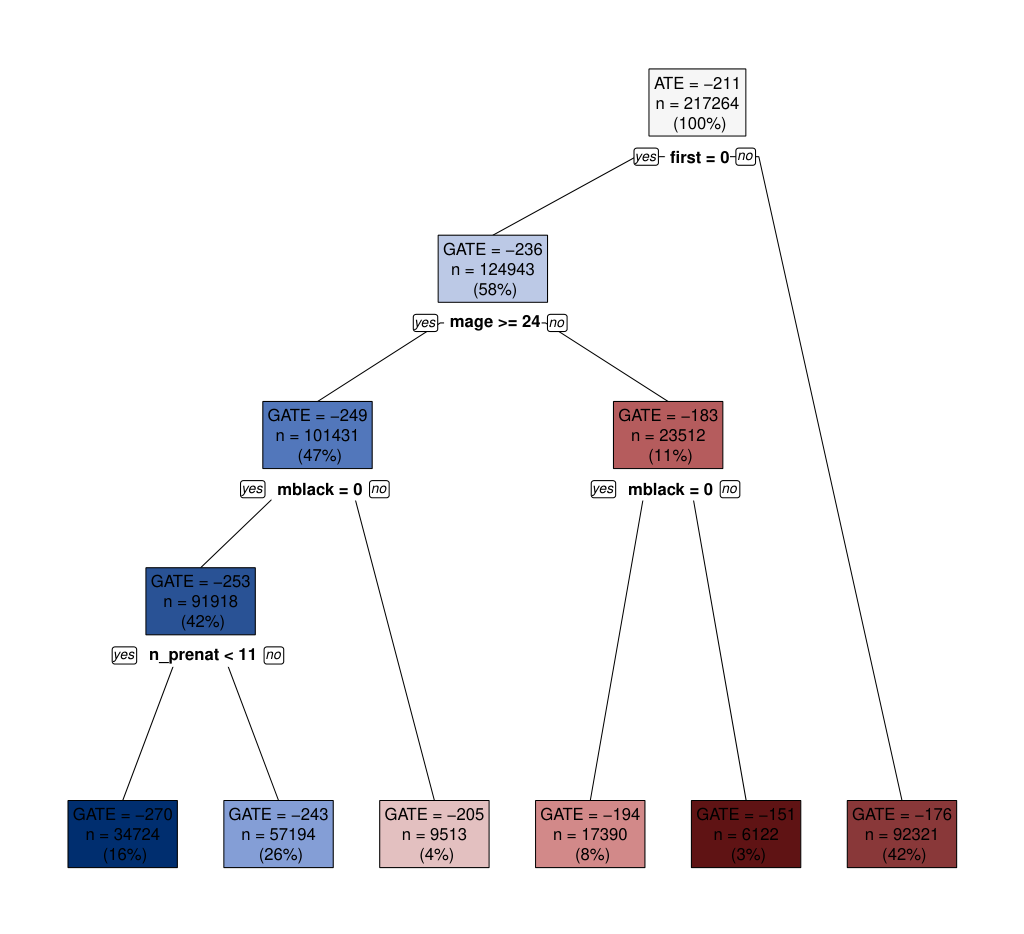
An aggregation tree splitting births into subgroups with different effects of maternal smoking on birth weight

R. Di Francesco, "Aggregation trees," Econometric Reviews 45, no. 5 (2026): 634–659. doi:10.1080/07474938.2025.2610309

Causal inferenceHeterogeneous effectsMachine learningHealth

Who responds most to a treatment? Aggregation trees let the data pick the subgroups without giving up valid inference. Revisiting maternal smoking, we find that the birth-weight penalty is largest for adult mothers and for those who start prenatal care early.

Paper R package
Abstract
Uncovering the heterogeneous effects of particular policies or "treatments" is a key concern for researchers and policymakers. A common approach is to report average treatment effects across subgroups based on observable covariates. However, the choice of subgroups is crucial, as it poses the risk of p-hacking and requires balancing interpretability with granularity. This article proposes a non parametric approach to construct heterogeneous subgroups. The approach enables a flexible exploration of the trade-off between interpretability and the discovery of more granular heterogeneity by constructing a sequence of nested groupings, each with an optimality property. By integrating our approach with "honesty" and debiased machine learning, we provide valid inference about the average treatment effect of each group. We validate the proposed methodology through an empirical Monte Carlo study and apply it to revisit the impact of maternal smoking on birth weight. Consistent with prior research, we find stronger effects for children born to adult mothers. We further provide novel evidence that effects are more pronounced when prenatal care begins earlier.
causalQual R package logo

R. Di Francesco and G. Mellace, "Causal inference for qualitative outcomes," Economics Letters (2025): 112626.

Causal inferenceQualitative outcomes

What is a treatment effect when the outcome is "good", "fair", or "poor"? Assigning numbers to categories can mislead. We propose estimands that track how treatment moves people across categories, identified under the same IV, RDD, and DiD assumptions you already use.

Paper R package Podcast
Abstract
Causal inference methods such as instrumental variables, regression discontinuity, and difference-in-differences are widely used to identify and estimate treatment effects. However, when outcomes are qualitative, their application poses fundamental challenges. This paper highlights these challenges and proposes an alternative framework that focuses on well-defined and interpretable estimands. We show that conventional identification assumptions suffice for identifying the new estimands and outline simple, intuitive estimation strategies that remain fully compatible with conventional econometric methods. We provide an accompanying open-source R package, causalQual, which is publicly available on CRAN.
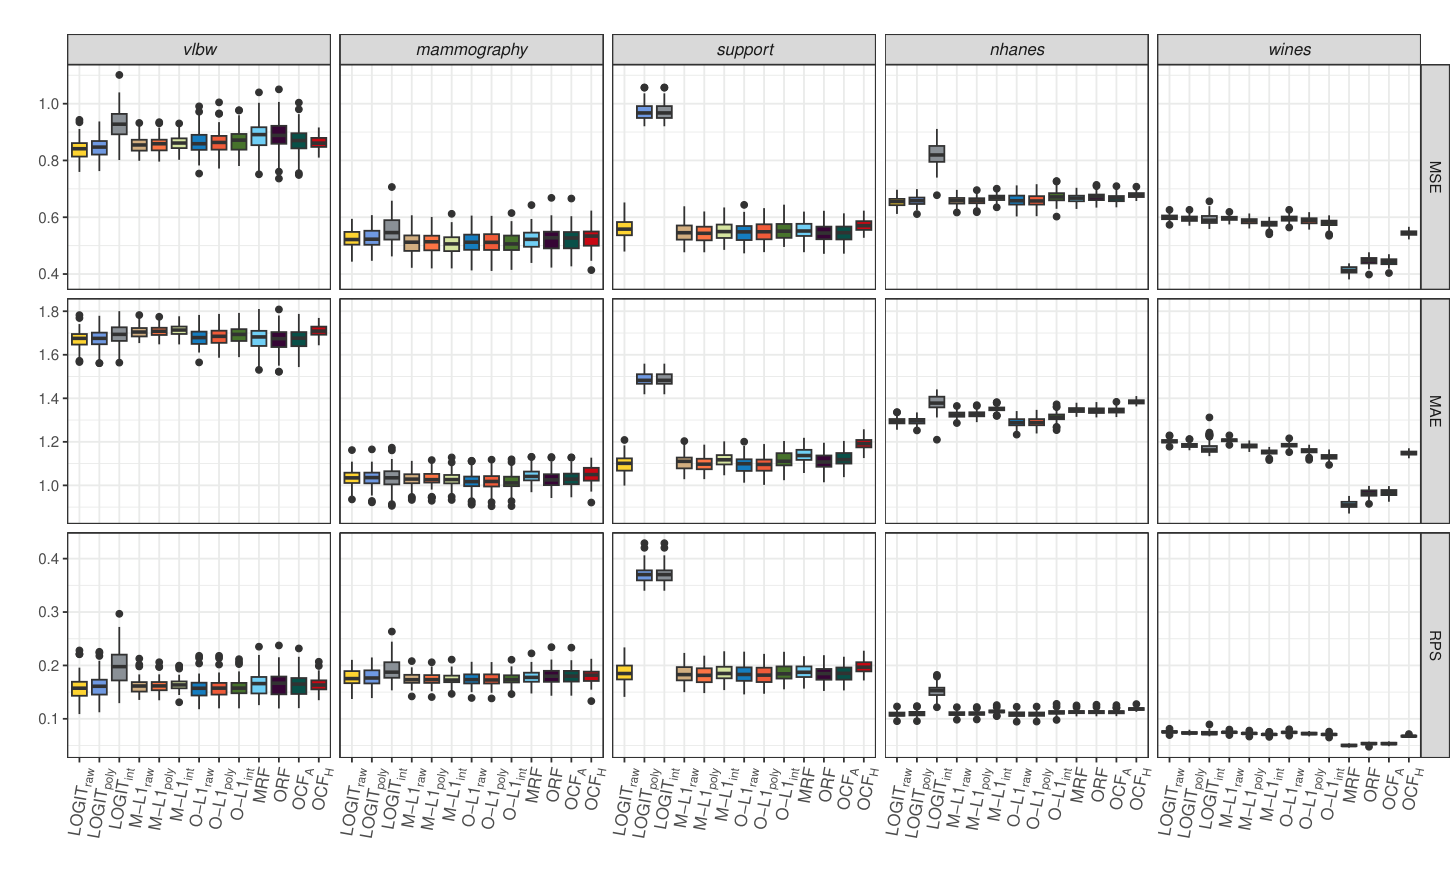
Boxplots of prediction performance across five real data sets, comparing the ordered correlation forest with parametric and forest-based estimators

R. Di Francesco, "Ordered correlation forest," Econometric Reviews 44, no. 4 (2025): 416–432. doi:10.1080/07474938.2024.2429596

Qualitative outcomesMachine learningEmerging Econometrician award

Ordered logit and probit are the default for outcomes like self-rated health, but they come with strong assumptions. The ordered correlation forest drops those assumptions and still delivers marginal effects with valid confidence intervals.

Paper R package Award Press Podcast
Abstract
Empirical studies in various social sciences often involve categorical outcomes with inherent ordering, such as self-evaluations of subjective well-being and self-assessments in health domains. While ordered choice models, such as the ordered logit and ordered probit, are popular tools for analyzing these outcomes, they may impose restrictive parametric and distributional assumptions. This article introduces a novel estimator, the ordered correlation forest, that can naturally handle non linearities in the data and does not assume a specific error term distribution. The proposed estimator modifies a standard random forest splitting criterion to build a collection of forests, each estimating the conditional probability of a single class. Under an "honesty" condition, predictions are consistent and asymptotically normal. The weights induced by each forest are used to obtain standard errors for the predicted probabilities and the covariates' marginal effects. Evidence from synthetic data shows that the proposed estimator features a superior prediction performance than alternative forest-based estimators and demonstrates its ability to construct valid confidence intervals for the covariates' marginal effects. Comparisons using various real-world data sets further highlight the advantages of forest-based estimators over parametric models in larger samples while showing that the ordered correlation forest remains competitive in smaller samples.

Working papers

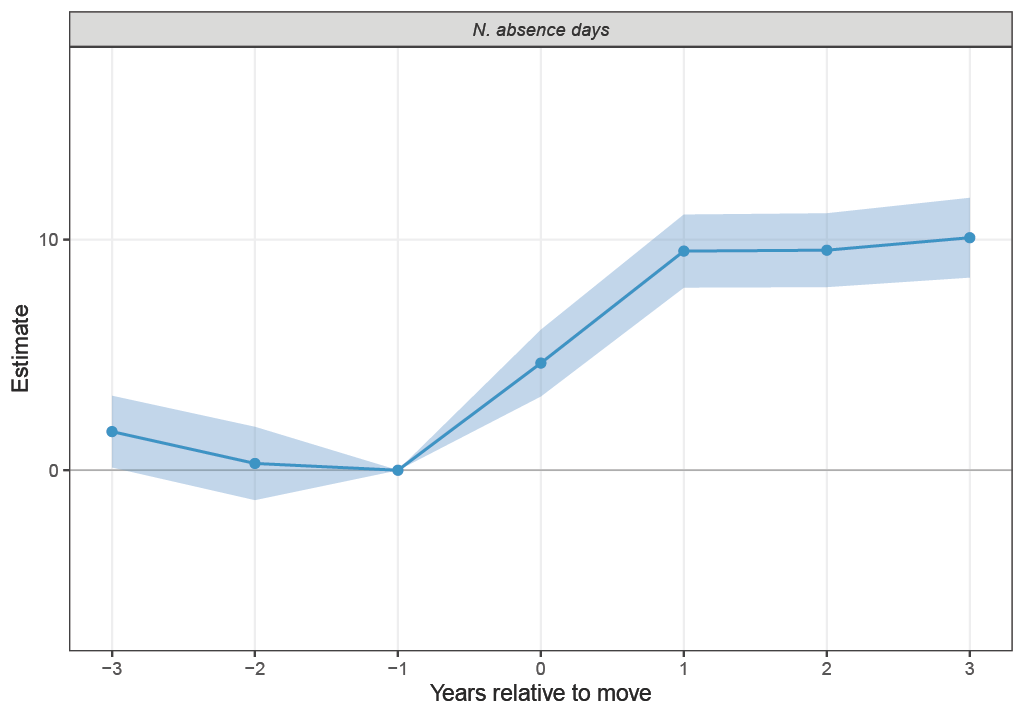
Event-study estimates: absence days rise by about ten after a move to a firm that puts more weight on well-being

R. Di Francesco, P. Hull, and S. Menon, "Well-being salience in corporate disclosures and worker health," NBER Working Paper 35760, 2026.

Causal inferenceHealthLaborText as data

Does it matter when your employer talks about well-being? We use language models to measure how much Danish firms' public disclosures emphasize employee well-being, and follow workers who switch firms. Moving to a firm that puts more weight on well-being raises sickness absence but not health-care use: workers act differently on their health, not because it got worse.

Paper Slides
Abstract
We study how firms' orientation toward employee well-being shapes the health of their workers. Because this orientation is not directly observable, we measure it from the language Danish firms use in their public disclosures, applying language models to construct a firm-level well-being salience score. We link this score to population-wide administrative registers of health and sickness absence over 2013–2022, and exploit workers' mobility between firms to estimate how workers respond to a change in the salience of their employer. We find an asymmetry: workers who move to higher-salience firms take substantially more sickness absence, while their use of health care does not change. Because worsening health would raise both, the absence response suggests a behavioral change rather than deteriorating health. Broadly, our results show that firms shape not only worker health but how workers act on it, and that the language of routine corporate disclosure can reveal economically meaningful features of the workplace that administrative data leave unrecorded.
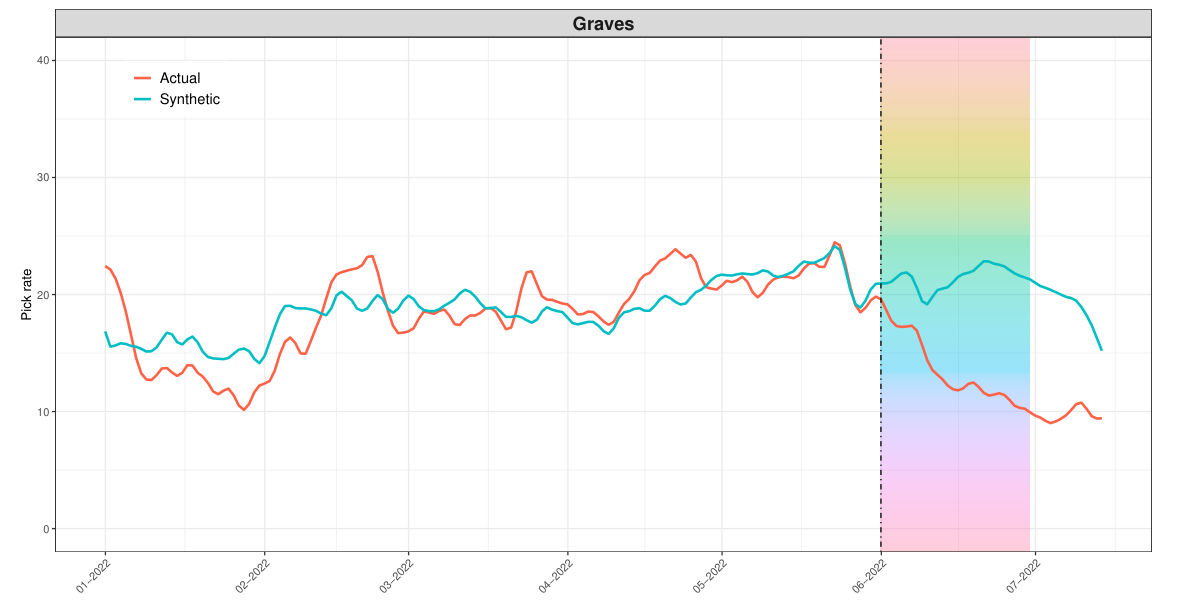
Daily pick rates for a game character, actual versus synthetic control, diverging after the coming-out event

E. Brox and R. Di Francesco, "Behavioral consequences of sexual orientation disclosure in a large-scale digital environment," arXiv:2403.03649, 2024.

Causal inferenceLGBT economicsOnline platforms

What happens when someone comes out? When a character from a popular online video game was revealed to be gay, players picked it about 40% less, even though nothing about how the character plays had changed.

Paper Podcast
Abstract
Many individuals hesitate to disclose their sexual orientation, anticipating that disclosure may alter how others respond to them. At the same time, concealing one's identity can entail substantial personal and social costs. Understanding how others react to sexual orientation disclosure is therefore central to evaluating the broader consequences of coming out. This paper uses an innovative data set from a popular online video game together with a natural experiment to causally identify behavioral responses to sexual minority disclosure. We exploit exogenous variation in the identity of a playable character to identify the effects of coming out on players' revealed preferences for that character across diverse regions globally. Our findings reveal a substantial and persistent negative impact of coming out.

Work in progress

  • "The value of coworker complementarities in team production" (with E. Brox)
  • "A local differencing test for the credibility of selection-on-observables" (with F. Peracchi)
  • "Validating machine learning predictions of heterogeneous treatment effects" (with M. C. Knaus)
  • "Joint ordered correlation forest"

© 2026 Riccardo Di Francesco


Built with Quarto